

Choose the framework by the problem you are actually solving, and keep Milvus as the stable layer underneath. If your challenge is getting answers out of a document collection, start with LlamaIndex or Haystack. If you are building an agent that calls tools and makes decisions, use LangChain with LangGraph, or Agno. If you want a visual, low-code app builder, use Dify. If you need to systematically improve prompts against a metric, add DSPy. Sentence Transformers is not an orchestration framework at all. It is the model library that produces the embeddings and reranking scores the others consume. All of them can use Milvus for storage and search, so the decision is about developer workflow, not about which one can talk to the database.
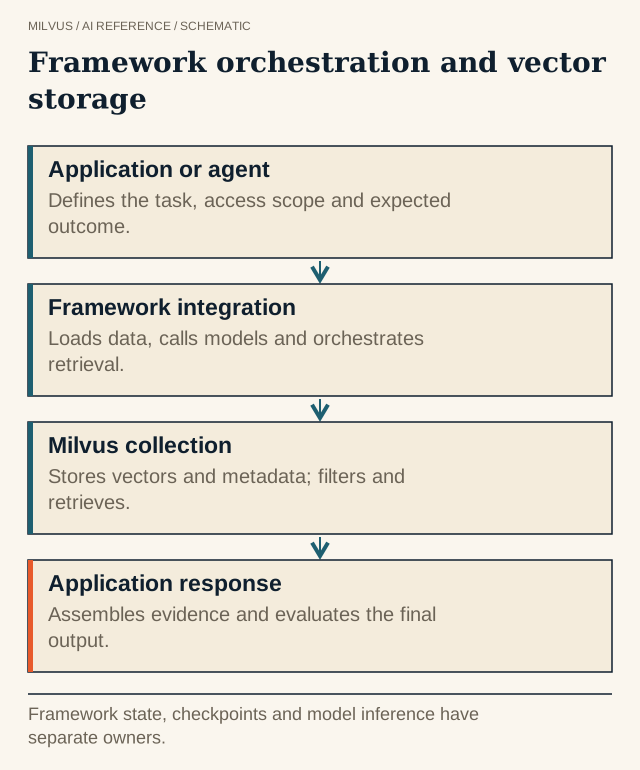 Framework orchestration and vector storage. Framework state, checkpoints and model inference have separate owners.
AI frameworks for Milvus compared
| Framework | What it is best at | How it uses Milvus | Pick it when |
|---|---|---|---|
| LangChain | Broad integrations: models, tools, retrievers, chains | langchain-milvus → Milvus vector store, BM25 hybrid, partition-key multi-tenancy | You want the largest ecosystem and a standard retriever interface |
| LangGraph | Stateful agent graphs with loops, checkpoints, human-in-the-loop | Milvus behind a retrieval tool or node | Your agent needs explicit control flow and resumable runs |
| LlamaIndex | Ingestion, node parsing, indexes, and query engines over private data | llama-index-vector-stores-milvus → MilvusVectorStore, metadata filters, hybrid mode | Retrieval quality over documents is the core problem |
| Haystack | Explicit, typed component pipelines | milvus-haystack → MilvusDocumentStore + dense, sparse, and hybrid retrievers | You want auditable pipelines you can test component by component |
| Dify | Visual app and workflow builder with built-in knowledge bases | VECTOR_STORE=milvus in the self-hosted deployment | Product teams need to build and iterate without much code |
| DSPy | Optimizing LM programs (prompts, few-shot examples) against a metric | A Python search function calling MilvusClient | You have labeled examples and want measurable prompt improvements |
| Agno | Lightweight agents with knowledge, memory, and tools | agno.vectordb.milvus.Milvus behind Knowledge | You want a compact agent framework with built-in knowledge search |
| Sentence Transformers | Running and fine-tuning embedding and reranking models | Produces the vectors you insert, plus cross-encoder reranking | You self-host open models for embeddings or reranking |
These tools combine well. A common stack is Sentence Transformers for embeddings, LlamaIndex or Haystack for ingestion, LangGraph for the agent loop, and Milvus underneath. Add a layer only when it solves a specific problem.
How should you decide? A short decision flow
- Start from the workload, not the hype. Write down the first real task. Examples: “answer support questions with citations from 40,000 help articles, filtered by product and tenant,” or “triage tickets and call three internal APIs.” The first is retrieval-centric. The second is agent-centric.
- Check who will build and maintain it. Engineers comfortable in Python will move fastest with LlamaIndex, LangChain, Haystack, or Agno. A mixed product team may prefer Dify’s UI. DSPy rewards teams that already think in datasets and metrics.
- Check the integration depth you need. Every wrapper covers insert, search, and metadata filters. The differences show up in hybrid BM25 search, multi-tenancy via partition keys, delete and update semantics, and custom index parameters. Read the integration page for each feature you depend on. If a wrapper does not expose one, you can always create and manage the collection with PyMilvus and point the framework at it.
- Build one thin end-to-end path with ingestion, filtered retrieval, cited answers, and a small evaluation set before adding agents, rerankers, or a second framework.
- Measure, then expand. Compare Recall@k, citation correctness, latency, and cost on the same questions. Keep the framework that improves those numbers or developer speed, and drop the ones that only add moving parts.
Keep the retrieval layer framework-independent
Frameworks change quickly. Imports move, classes are deprecated, and defaults shift between releases. Your data model should outlive all of that. Before you write framework code, decide these things yourself:
- Stable IDs for every source document and chunk, taken from your own system rather than generated by an adapter. Updates and deletes depend on them.
- Metadata fields you will filter on (tenant, product, version, language, access level), defined explicitly so every framework writes the same fields.
- The embedding model, revision, dimension, and metric. A wrapper’s default embedding model or metric may not suit your data. Set them explicitly and record them with the collection.
- The access-control rule. Tenant and permission filters are built by your application from the authenticated user and applied as Milvus filter expressions. They are never chosen by a prompt or a model. See how authentication, RBAC, and tenant filters protect Milvus applications.
With that contract in place, switching from one framework to another is a code change, not a data migration. You can also run two frameworks against the same collection to compare them fairly.
Verify what the integration actually does
A framework listing Milvus as “supported” tells you a connector exists. It does not tell you every Milvus feature is wired through. Before production, test with your pinned package versions:
- Insert documents with metadata, then confirm the fields exist in the collection, for example in Attu.
- Run a filtered search and confirm the filter is applied in Milvus, not by trimming results in Python.
- Update and delete a document, then confirm the old chunks are gone.
- Run the same query through the framework and through
MilvusClient.searchon the same collection. The IDs should match. - Break something on purpose, such as stopping the server or sending an empty result set, and check what the application does.
Then evaluate retrieval separately from generation, as described in how to evaluate retrieval quality. A fluent answer can hide a retrieval miss.
Where does Milvus fit regardless of framework?
Milvus supplies the parts no orchestration framework provides: dense, sparse, and hybrid search in one database, filtered ANN search at scale, multi-tenancy through partition keys, and deployment options that run from Milvus Lite in a notebook to a distributed cluster or managed Zilliz Cloud. The same uri and token connection works from every integration on this page.
Next steps
Get a Milvus instance running with the Milvus Quickstart, or create a managed cluster on Zilliz Cloud. Then follow the integration tutorial for your framework: LangChain, LlamaIndex, Haystack, LangGraph, or Dify. The Milvus Bootcamp has more end-to-end examples.
Related reading
- What is retrieval-augmented generation (RAG)?
- What is agentic search, and where does a vector database fit?
- What is hybrid search, and when should you use it?
- How should you build a reproducible application workflow with PyMilvus?


